Corpus plots
Plots for the corpus measures: the lexical dispersion - where in a text a word occurs, a chart of the keywords found by keyness and a network of the collocations found by collocations. The matplotlib functions take the axes ax and return Axes: without ax a new figure is created, with it the plot goes into a grid of one's own; the network of collocations is built by graphviz and returns a Graph, as the word tree returns a Digraph.
The functions are those of the anyTS core. The default labels of the matplotlib plots are the English ones of VISUALIZER_LABELS in anyts.constants; labels replaces any of them.
Lexical dispersion
dispersion_plot(words, targets, ax=None, labels=None)
A row for every word of targets and a tick at the position of each of its occurrences in the text. Words are compared as they are: case and lemmatization belong to the extraction of the words.
| Parameter | Type | Default | Description |
|---|---|---|---|
words |
list[str] |
- | Words of the text in order |
targets |
list[str] |
- | Words whose occurrences are shown |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel |
Words or targets that are not a list of strings raise SourceTypeError, no words or no targets SourceError; labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
The words are extracted by WordsExtractor: lower case with lowercase=True, lemmas with use_lexemes=True.
Chart of keywords
keyness_plot(positive, negative=(), top_n=20, labels=None, field='score', log=False, ax=None)
Diverging horizontal bars: the words of positive to the right, of negative (the result of keyness with positive=False) to the left, top_n on each side. The length of a bar is the absolute value of the field (score, g2, log_ratio), so the side is set by the list, not by the sign of the measure; words with an undefined or infinite value are skipped. For the odds ratio (from 0 to infinity, one - equal odds) log=True plots the absolute \(\log_2\) of the value, symmetric around one.
| Parameter | Type | Default | Description |
|---|---|---|---|
positive |
list[Keyword] |
- | Positive keywords |
negative |
list[Keyword] |
() |
Negative keywords |
top_n |
int |
20 |
Number of words on each side |
labels |
dict[str, str] / tuple[str, str] |
None |
Labels over the defaults: title, xlabel and xlabel_log (format strings with field), target and reference (the legend); a pair of strings sets the legend alone |
field |
str |
'score' |
Field of Keyword whose values are plotted |
log |
bool |
False |
Plot \(\log_2\) of the value - for the odds ratio |
ax |
Axes |
None |
Axes for the plot |
Keywords that are not a list raise SourceTypeError, and no keyword with a finite value SourceError. An unknown field, a top_n that is not an integer of at least one, labels that merge_labels refuses or a legend that is not a pair, and an ax that is not a matplotlib Axes raise ParameterError.
Network of collocations
collocation_network(collocations, top_n=None)
An undirected graph in the neato layout: the nodes are the words, the size of the font by frequency, the edges the pairs, the width and the label by the measure. A pair of a word with itself (a word repeated within the window) would be a loop and is left out before top_n. Rendering needs the executables of Graphviz; Jupyter displays the graph, and graph.render("network") saves a png file.
| Parameter | Type | Default | Description |
|---|---|---|---|
collocations |
list[Collocation] |
- | Collocations |
top_n |
int |
None |
Number of pairs from the start of the list; None - all of them |
Collocations that are not a list raise SourceTypeError, no pair of two different words SourceError, and a top_n that is not an integer of at least one ParameterError.
The plots of Marianela by Galdós and of six novels from the corpus of literature - Marianela, Misericordia and Torquemada en la hoguera against Niebla, Abel Sánchez and La tía Tula by Unamuno:
from spacy.lang.es.stop_words import STOP_WORDS

from ests import WordsExtractor
from ests.corpus import collocations, keyness
from ests.datasets import SpanishLiterature
from ests.visualizers import collocation_network, dispersion_plot, keyness_plot

sl = SpanishLiterature()
sl.download()
titles = (
    "Marianela",
    "Misericordia",
    "Torquemada en la hoguera",
    "Niebla",
    "Abel Sánchez",
    "La tía Tula",
)
novels = {
    record["title"]: record["text"]
    for author in ("galdos", "unamuno")
    for record in sl.get_records(author=author)
    if record["title"] in titles
}

# Where the characters and the motifs of Marianela occur
words = WordsExtractor(lowercase=True).extract(novels["Marianela"])
dispersion_plot(words, ["nela", "pablo", "florentina", "golfín", "ciego", "luz"])

# Keywords of Galdós against Unamuno, lemmas without stop words
we = WordsExtractor(use_lexemes=True, lowercase=True, filter_nums=True, stopwords=STOP_WORDS)
galdos = [lemma for title in titles[:3] for lemma in we.extract(novels[title])]
unamuno = [lemma for title in titles[3:] for lemma in we.extract(novels[title])]
keyness_plot(
    keyness(galdos, unamuno, min_freq=5, top_n=10),
    keyness(galdos, unamuno, positive=False, min_freq=5, top_n=10),
    labels=("Galdós", "Unamuno"),
)

# Network of collocations of Marianela
graph = collocation_network(
    collocations(we.extract(novels["Marianela"]), window=3, min_freq=5, top_n=25)
)
graph.render("network", format="png")
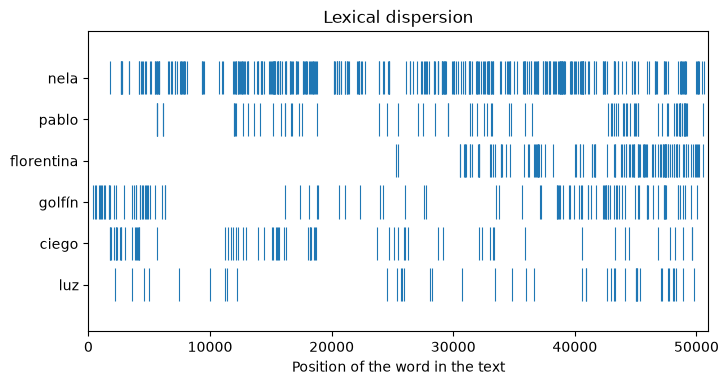
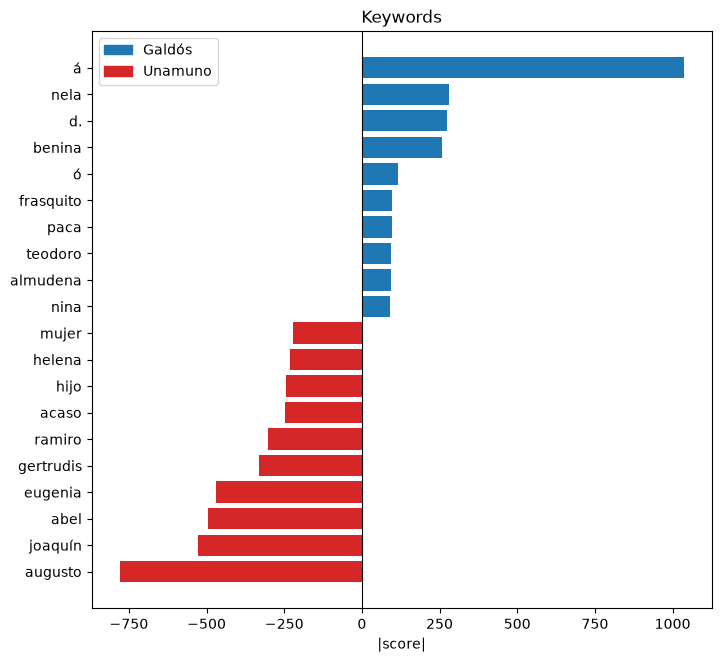
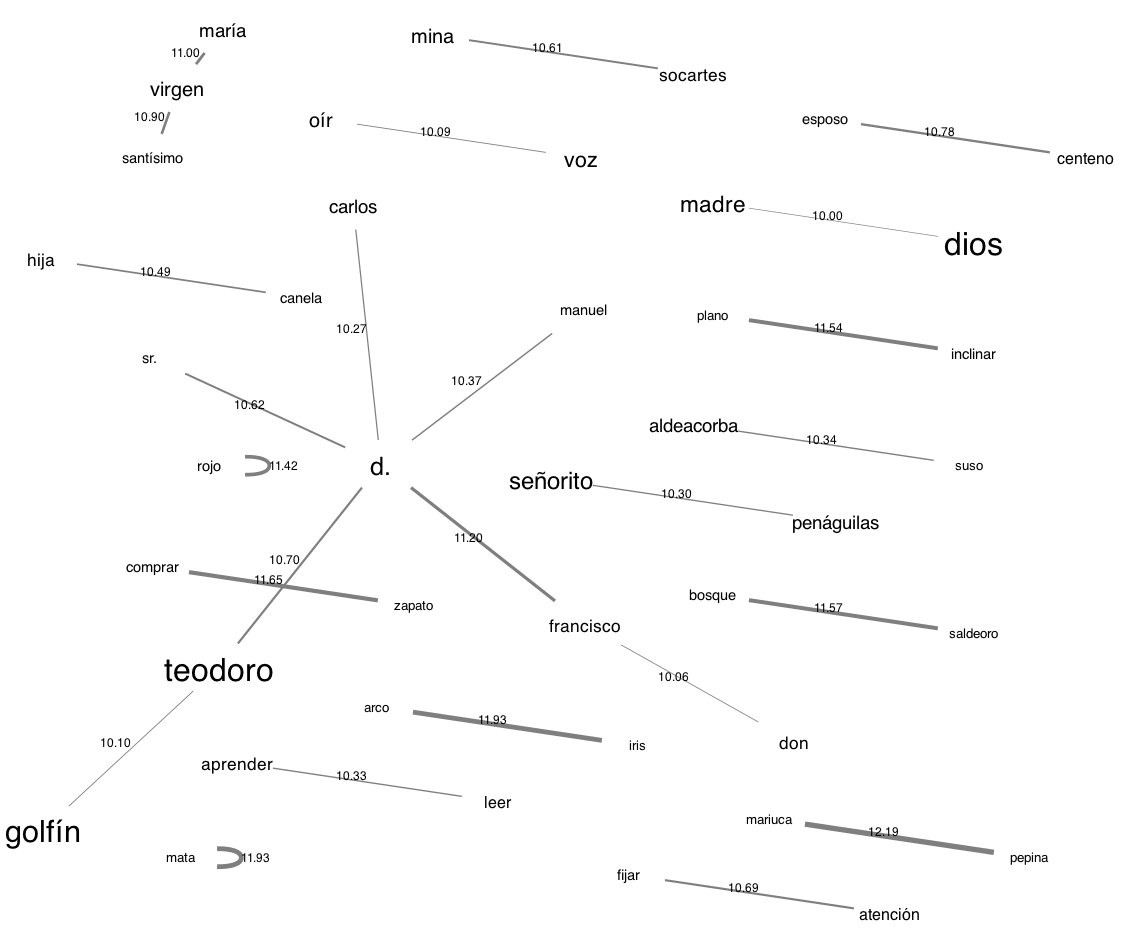
Nela runs through the whole novel, Florentina enters in its second half, and the doctor Golfín opens and closes it; the blindness of Pablo (ciego) belongs mostly to the first half. Beside the names of the characters, the keywords show the old spelling of the editions (á, fué) and words of the themes of Unamuno: acaso, hijo. The network of collocations gathers the names and the places of Marianela around d., the abbreviated don: Teodoro Golfín, Aldeacorba de Suso, the mines of Socartes.