Vocabulary growth and frequency spectrum
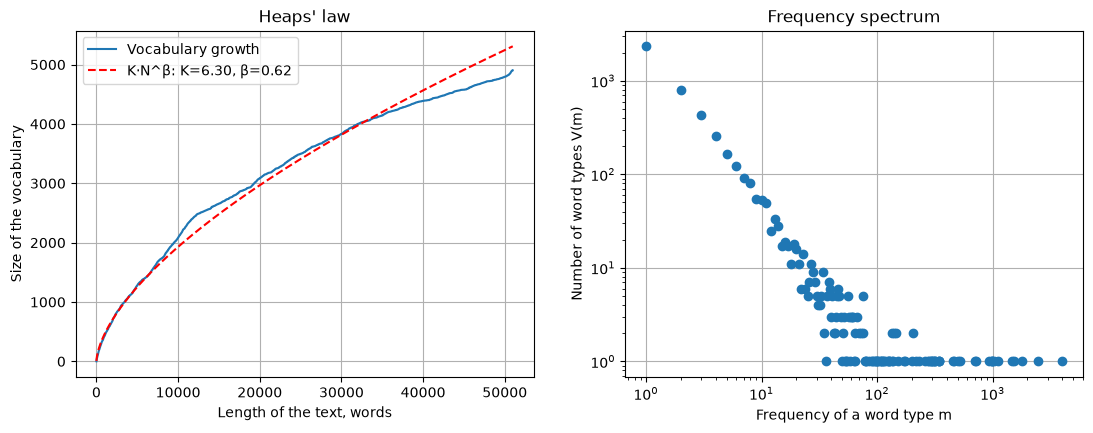
Two plots of the distribution of the words of a text that complement Zipf's law: the growth of the vocabulary with the length of the text by Heaps' law and the frequency spectrum - how many word types occur exactly once, twice, three times. The functions take the axes ax and return Axes.
The functions are those of the anyTS core; the fit of Heaps' law is described in fit_heaps and the spectrum in calc_frequency_spectrum. The default labels are the English ones of VISUALIZER_LABELS in anyts.constants; labels replaces any of them.
Heaps' law
heaps_plot(words, ax=None, labels=None)
The size of the vocabulary \(V\) after every word of the text and the fitted curve \(V(N) = K \cdot N^{\beta}\) of fit_heaps with its parameters in the legend; the curve depends on the order of the words.
| Parameter | Type | Default | Description |
|---|---|---|---|
words |
list[str] |
- | Words of the text in order |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel, ylabel, growth (the curve), fit (a format string with k and beta) |
Words that are not a list of strings raise SourceTypeError, fewer than two words SourceError; labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
Frequency spectrum
frequency_spectrum_plot(words, ax=None, labels=None)
The number of word types \(V(m)\) that occur exactly \(m\) times (calc_frequency_spectrum) in logarithmic coordinates; the left edge is the hapaxes. The spectrum underlies the measures of diversity of Yule, Sichel, Michéa and Honoré, and its shape shows how far the vocabulary of the text is from being exhausted.
| Parameter | Type | Default | Description |
|---|---|---|---|
words |
list[str] |
- | Words of the text |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel, ylabel |
Words that are not a list of strings raise SourceTypeError, no words SourceError; labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
The plots of the lemmas of Marianela by Galdós from the corpus of literature:
import matplotlib.pyplot as plt

from ests import WordsExtractor
from ests.datasets import SpanishLiterature
from ests.visualizers import frequency_spectrum_plot, heaps_plot

sl = SpanishLiterature()
sl.download()
text = next(
    record["text"] for record in sl.get_records(author="galdos") if record["title"] == "Marianela"
)
lemmas = WordsExtractor(use_lexemes=True, lowercase=True, filter_nums=True).extract(text)

fig, (left, right) = plt.subplots(1, 2, figsize=(13, 4.5))
heaps_plot(lemmas, ax=left)
frequency_spectrum_plot(lemmas, ax=right)