Stylometric plots
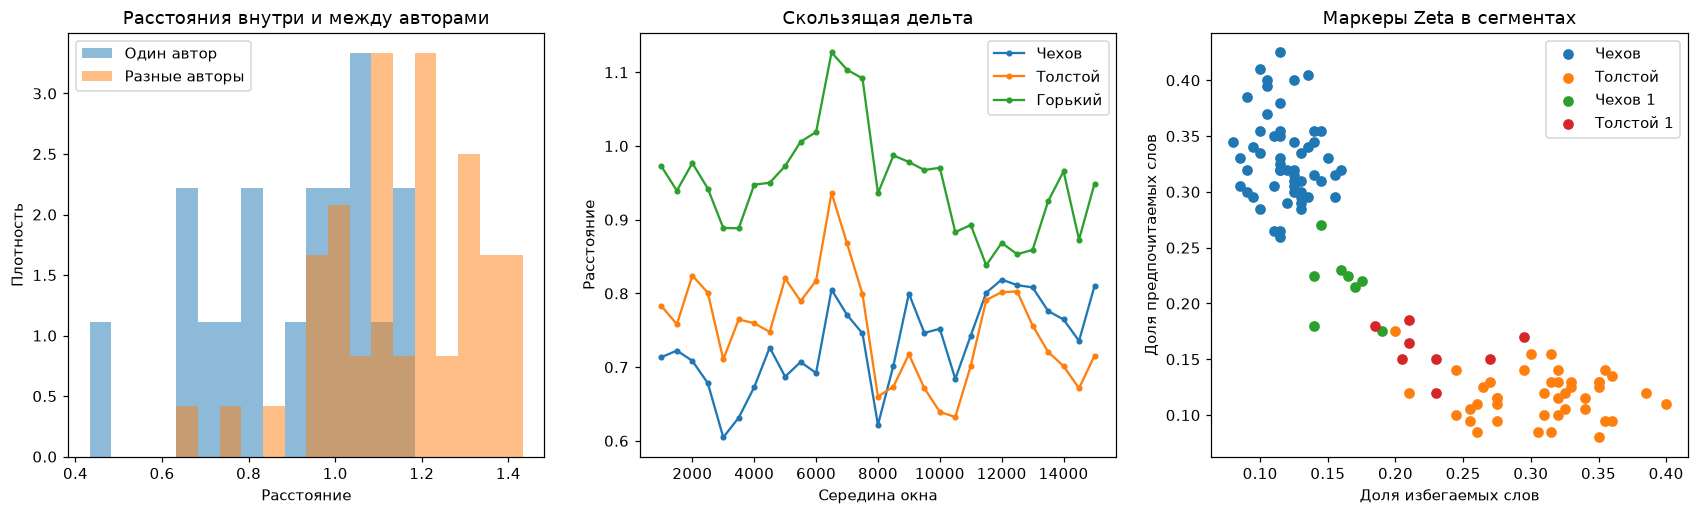
Plots for stylometry: a dendrogram, multidimensional scaling and histograms of the distances within and between authors from the delta distance matrix, a principal component chart from the frequencies of the most frequent words, the distances of rolling Delta along a text, the segments of corpora by the markers of Zeta and Mendenhall curves of several texts. The functions take axes ax and return Axes.
The functions are those of the anyTS core with the Russian labels of ruts.constants.VISUALIZER_LABELS by default; labels puts the given labels over them. The frequencies of the principal components come from frequency_table, the distances along a text from rolling_delta, the segments from zeta_segments and the curves from mendenhall_curve.
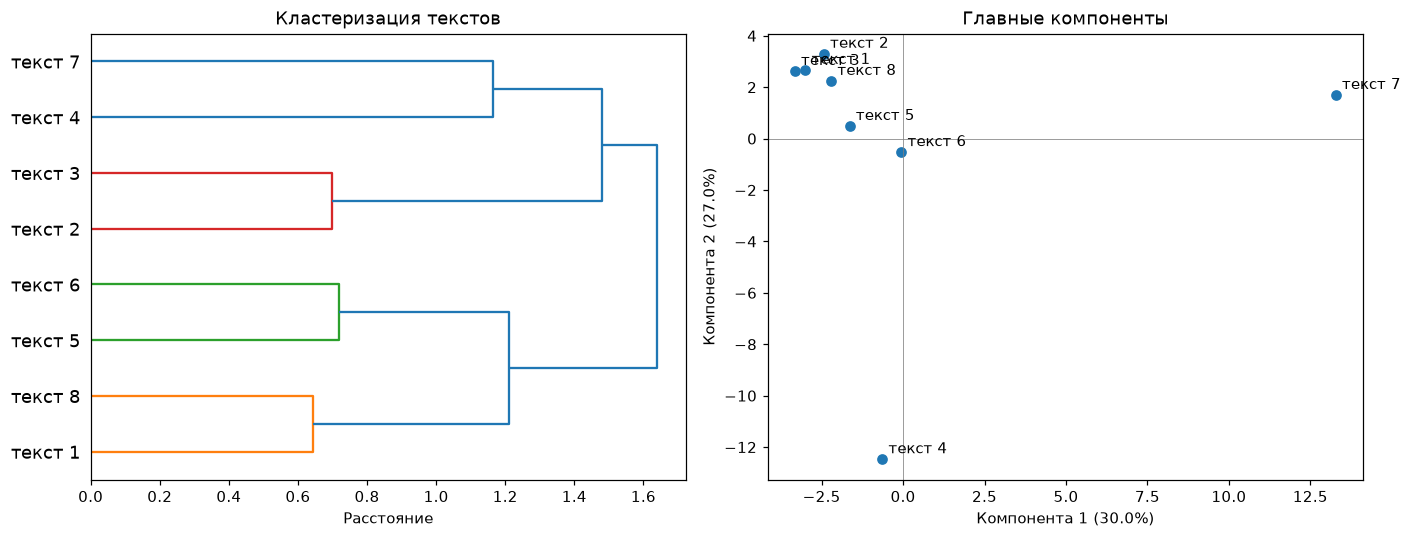
Dendrogram
dendrogram_plot(distances, method='ward', ax=None, labels=None)
Hierarchical clustering by scipy.cluster.hierarchy over the matrix of distances between texts, Ward's method by default as in Evert et al. (2015); the leaves are labelled by the index of the matrix. The columns are taken in the order of the rows.
| Parameter | Type | Default | Description |
|---|---|---|---|
distances |
DataFrame |
- | Symmetric matrix of distances with the names of the texts in the rows and the columns, in any order |
method |
str |
'ward' |
Method of scipy.cluster.hierarchy.linkage to join the clusters: single, complete, average, weighted, centroid, median or ward |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel |
Other texts in the columns than in the rows, fewer than two texts, an infinite or negative distance, asymmetry or a distance on the diagonal raise SourceError before a figure is created. Distances that are not a DataFrame of numbers raise SourceTypeError; an unknown method, labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
Principal components
pca_plot(corpus, n_mfw=100, culling=0.0, ax=None, labels=None)
Principal component analysis of the z-scores of the relative frequencies of the most frequent units (frequency_table, z_scores): the texts on the plane of the first two components with their names, the shares of the explained variance in the labels of the axes.
| Parameter | Type | Default | Description |
|---|---|---|---|
corpus |
dict[str, list[str]] |
- | Units of the texts by the names of the texts |
n_mfw |
int |
100 |
Number of the most frequent units; None - all of them |
culling |
float |
0.0 |
Smallest share of the texts a unit occurs in |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel and ylabel (format strings with the explained share) |
The corpus, n_mfw and culling raise the errors of frequency_table, and fewer than three texts raise SourceError; labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
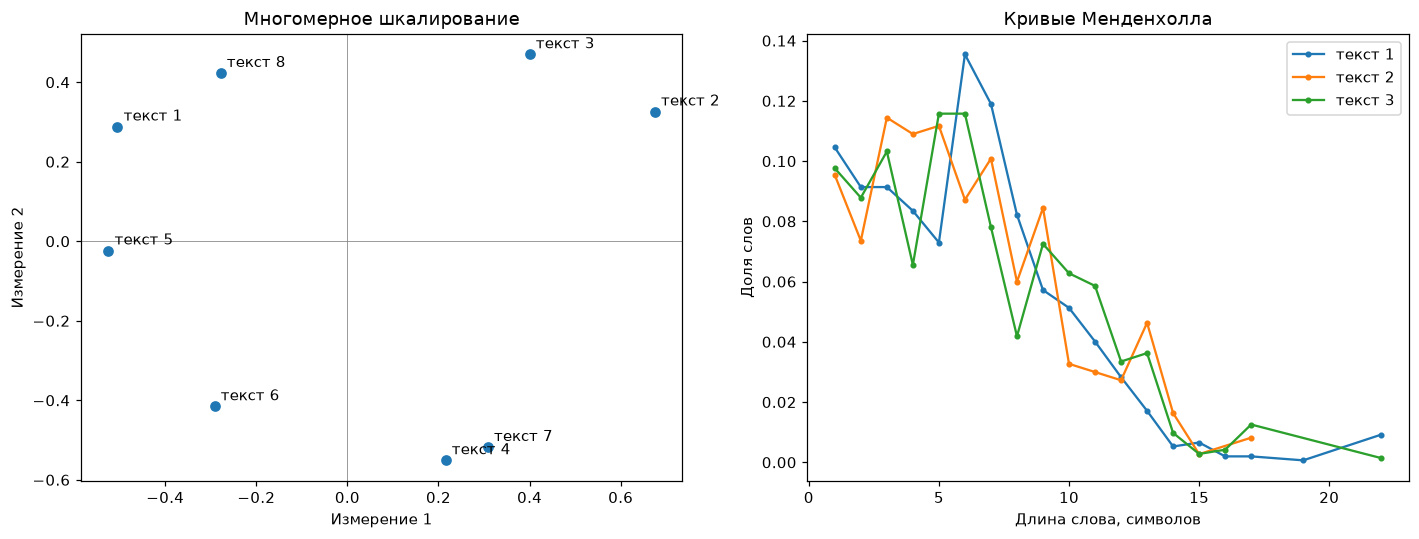
Multidimensional scaling
mds_plot(distances, ax=None, labels=None)
Classical multidimensional scaling (Torgerson 1952) of any matrix of distances: the two leading eigenvectors of the double-centred squared distances, so the distances between the points approximate those of the matrix. The columns are taken in the order of the rows.
| Parameter | Type | Default | Description |
|---|---|---|---|
distances |
DataFrame |
- | Symmetric matrix of distances with the names of the texts in the rows and the columns, in any order |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel, ylabel |
Other texts in the columns than in the rows, fewer than two texts, an infinite or negative distance, asymmetry or a distance on the diagonal raise SourceError before a figure is created. Distances that are not a DataFrame of numbers raise SourceTypeError; labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
Distances within and between authors
delta_histogram_plot(distances, authors, bins=20, ax=None, labels=None)
The histograms of the distances of the pairs of texts by one author and of the pairs by different authors, as densities over common bins, so groups of different sizes are comparable. The less the histograms overlap, the better the distances tell the authors apart - a check of the number of units and of the variant of Delta on texts of known authors. The columns are taken in the order of the rows.
| Parameter | Type | Default | Description |
|---|---|---|---|
distances |
DataFrame |
- | Symmetric matrix of distances with the names of the texts in the rows and the columns, in any order |
authors |
dict[str, str] |
- | Authors of the texts by the names of the texts |
bins |
int |
20 |
Number of the bins, at most 1000 |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel, ylabel and the legend within, between |
The matrix raises the errors of dendrogram_plot; authors that are not a mapping raise SourceTypeError, and a text without an author, no two texts by one author or all of them by one author SourceError. A bins that is not an integer from 1 to 1000, labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
Rolling Delta
rolling_delta_plot(distances, ax=None, labels=None)
The distances of rolling_delta as a line for every reference text over the middles of the windows: the lowest line is the nearest reference of a part of the text, and where the lines cross, the style changes.
| Parameter | Type | Default | Description |
|---|---|---|---|
distances |
DataFrame |
- | Distances of rolling_delta: the windows by the position of their middle in the rows, the reference texts in the columns |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel, ylabel |
Distances that are not a DataFrame of numbers with numbers in the index raise SourceTypeError; no windows or no reference texts, a position that is not finite and an infinite or negative distance raise SourceError before a figure is created. Labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
Zeta scatter
zeta_scatter_plot(segments, ax=None, labels=None)
The segments of zeta_segments on the plane of the shares of the avoided words (horizontal axis) and of the preferred ones (vertical axis), a colour for every corpus, as in oppose of stylo.
| Parameter | Type | Default | Description |
|---|---|---|---|
segments |
DataFrame |
- | Segments of zeta_segments with the columns corpus, preferred and avoided |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel, ylabel |
Segments that are not a DataFrame or shares that are not numbers raise SourceTypeError; a missing or repeated column, no segments and a share that is not finite raise SourceError before a figure is created. Segments without the name of a corpus (NaN) are drawn as a corpus of their own. Labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
Mendenhall curves
mendenhall_plot(corpus, ax=None, labels=None)
The shares of the words by length in characters (mendenhall_curve) of every text on one plot; a length no word has is drawn at zero.
| Parameter | Type | Default | Description |
|---|---|---|---|
corpus |
dict[str, list[str]] |
- | Words of the texts by the names of the texts |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel, ylabel |
A corpus that is not a mapping of lists of strings raises SourceTypeError, no texts or a text without words SourceError; labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
The plots of 8 texts of the StalinWorks dataset:
import matplotlib.pyplot as plt

from ruts import WordsExtractor
from ruts.corpus import delta
from ruts.datasets import StalinWorks
from ruts.visualizers import dendrogram_plot, mds_plot, mendenhall_plot, pca_plot

we = WordsExtractor(use_lexemes=True, lowercase=True, filter_nums=True)
texts = StalinWorks().get_texts(limit=8)
corpus = {f"текст {i + 1}": we.extract(text) for i, text in enumerate(texts)}
distances = delta(corpus, n_mfw=100, variant="cosine")

fig, (left, right) = plt.subplots(1, 2, figsize=(13, 5))
dendrogram_plot(distances, ax=left)
pca_plot(corpus, n_mfw=100, ax=right)

fig, (left, right) = plt.subplots(1, 2, figsize=(13, 5))
mds_plot(distances, ax=left)
mendenhall_plot({name: corpus[name] for name in list(corpus)[:3]}, ax=right)
The plots of 12 works by Chekhov, Tolstoy and Gorky of the prose genre of the RussianLiterature dataset: the distances between all the works, rolling Delta over the first work of Chekhov followed by the first work of Tolstoy with the other three works of each author as the references, and the segments by the markers of Zeta of Chekhov against Tolstoy:
from ruts.corpus import rolling_delta, zeta, zeta_segments
from ruts.datasets import RussianLiterature
from ruts.visualizers import delta_histogram_plot, rolling_delta_plot, zeta_scatter_plot

names = ("Чехов", "Толстой", "Горький")
rl = RussianLiterature()
corpus, authors = {}, {}
for author in names:
    texts = rl.get_texts(genre="prose", author=author, min_len=40000, max_len=200000, limit=4)
    for i, text in enumerate(texts, 1):
        corpus[f"{author} {i}"] = we.extract(text)
        authors[f"{author} {i}"] = author
known = {author: [corpus[f"{author} {i}"] for i in (2, 3, 4)] for author in names}
reference = {author: [word for words in known[author] for word in words] for author in names}
scores = zeta(known["Чехов"], known["Толстой"], segment_size=1000)
preferred = [score.word for score in scores[:200]]
avoided = [score.word for score in scores[-200:]]
corpora = {
    "Чехов": known["Чехов"],
    "Толстой": known["Толстой"],
    "Чехов 1": corpus["Чехов 1"],
    "Толстой 1": corpus["Толстой 1"],
}

fig, axes = plt.subplots(1, 3, figsize=(19, 5))
delta_histogram_plot(delta(corpus, n_mfw=100, variant="cosine"), authors, ax=axes[0])
rolling_delta_plot(
    rolling_delta(reference, corpus["Чехов 1"] + corpus["Толстой 1"], window=2000, step=500),
    ax=axes[1],
)
zeta_scatter_plot(zeta_segments(corpora, preferred, avoided, segment_size=1000), ax=axes[2])