Sentence lengths
sentence_lengths_plot(source, window=10, inset=True, ax=None, labels=None, sents_extractor=None, words_extractor=None)
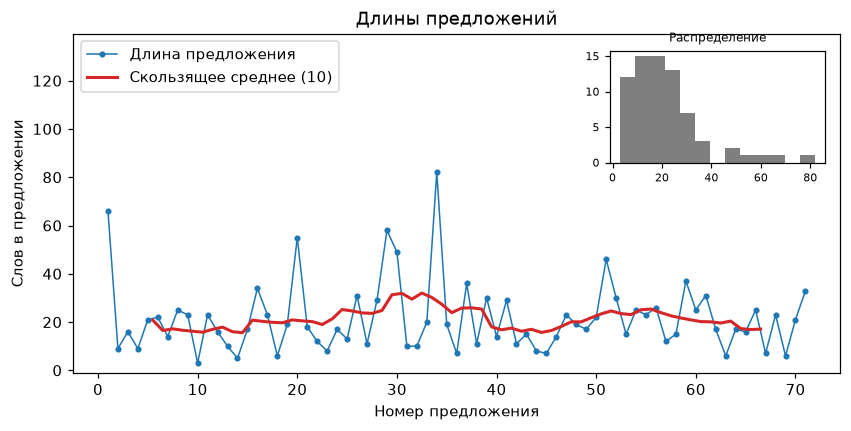
The curve of the lengths of the sentences - the rhythm of a text: the length of every sentence in words, in order, the moving average over window sentences and an inset with the histogram of the lengths. Short and long sentences in turn are an editorial sign of a lively text, a flat curve of a monotonous one. The function takes the axes ax and returns Axes.
The functions are those of the anyTS core; for a string ruTS passes its Russian SentsExtractor and WordsExtractor by default, and the sents_extractor and words_extractor parameters replace them. The default labels are the Russian ones of ruts.constants.VISUALIZER_LABELS; labels puts the given labels over them.
The curve of the first text of the StalinWorks dataset:
from ruts.datasets import StalinWorks
from ruts.visualizers import sentence_lengths_plot

text = next(StalinWorks().get_texts(limit=1))
sentence_lengths_plot(text, window=10)
Parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
source |
str / Doc / Iterable[int] |
- | Text, Doc object or lengths of the sentences (a list, a numpy array, a Series) |
window |
int |
10 |
Window of the moving average in sentences |
inset |
bool |
True |
Show the inset with the histogram |
ax |
Axes |
None |
Axes for the plot |
labels |
dict[str, str] |
None |
Labels over the defaults: title, xlabel, ylabel, length (the curve), average (a format string with window), distribution (the inset) |
sents_extractor |
SentsExtractor |
None |
Extractor of the sentences of a string; the sentence extractor of the library by default |
words_extractor |
WordsExtractor |
None |
Extractor of the words of a sentence of a string; the word extractor of the library by default |
The source and the extractors raise the errors of sentence_lengths, and no sentences raise SourceError; a window that is not an integer of at least one, labels that merge_labels refuses and an ax that is not a matplotlib Axes raise ParameterError.
Lengths of the sentences
sentence_lengths(source, sents_extractor=None, words_extractor=None)
The lengths of the sentences in words, in order: a string is split by the sentence and the word extractors, a Doc by its boundaries and tokens, punctuation and symbols left out and the parts of a hyphenated word joined (во-первых is one word); a Doc without boundaries or with partial ones (has_sents) is counted as its text. Sentences without words are skipped. Ready lengths (non-negative integers in a sequence or an iterator) are used as they are. The arguments are those of sentence_lengths_plot.
A table, a set, a mapping, bytes, a length that is not an integer and an extractor of another type raise SourceTypeError, a negative length SourceError.
from ruts.visualizers import sentence_lengths

sentence_lengths("Кот спит. Где пёс? - Ест, - сказала она.")
sentence_lengths(text)[:5]
[2, 2, 3]
[66, 9, 16, 9, 21]